Systems of record
In a fleet of agents every durable fact goes into a store built to be queried. A stray file is not a record, and a silent worker is not a status.

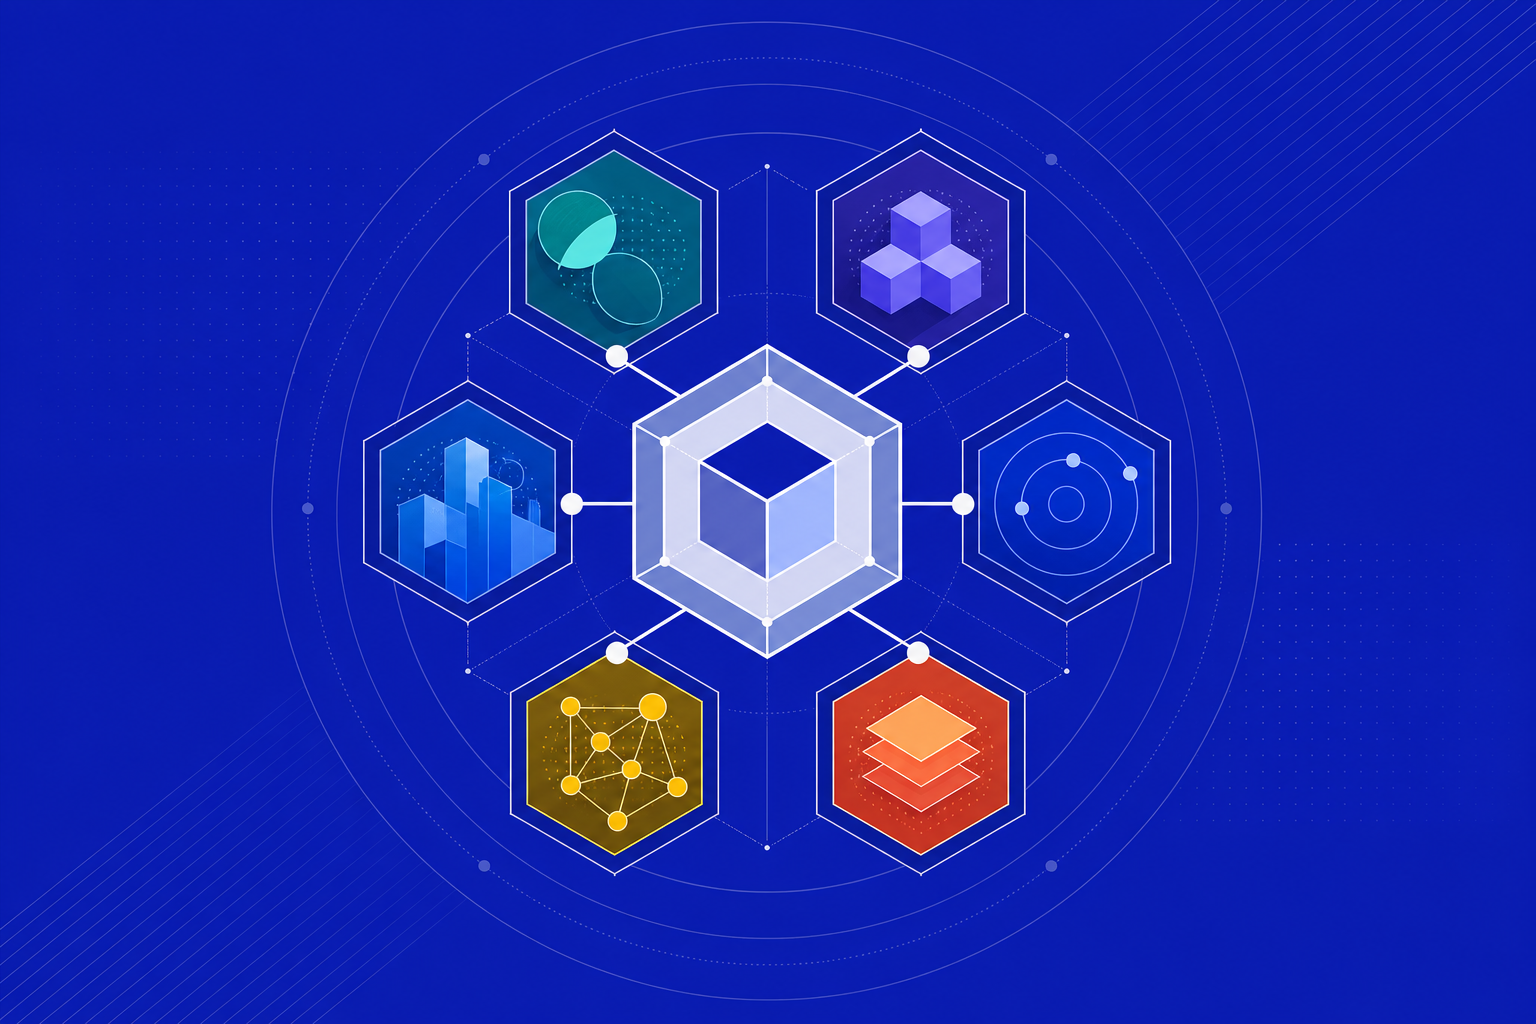
Every durable fact about how we operate lives in a store built to hold it: tasks in a task tracker, lessons in a memory store, what the agents say to each other in a messaging system, lasting notes in a knowledge store. Nothing durable lives in a file an agent dropped somewhere because that was quicker than calling the right tool. I work with a fleet of AI agents running on several machines around the clock, and a fleet cannot be walked the way a team’s floor can, so the record is the only way to know what is happening.
What is a record for?
So that a failure costs less the second time. The cleanest case I have is a prompt bar bug in one of our terminal applications. It broke once and was fixed, and the fix was posted to our conversation store, whose whole job is to be searchable, instead of being left in someone’s memory or in a pull request comment nobody rereads. Months later the same bug came back. The instruction for the second fix was to first read how we fixed it last time. The record existed and was consulted.
Failures still repeat. When they do, the second fix takes five minutes of reading instead of another hour of rediscovery.
A record matters just as much when the news is bad. A loop that triages product feedback hit the same wall run after run: its access could not reach the endpoint it needed. It did not investigate from zero each time. It pulled up a saved memory of the diagnosis and went straight to the same conclusion: still blocked, nothing changed, here is why. It also declined a shortcut. A credential that would have unblocked it immediately was within reach, but it was not sanctioned for an unattended process, so the loop left it alone.
That record, honest and searchable, is worth more than a green checkmark would have been. The job of a record is to make the actual state of things impossible to lose, including when the state is poor.
The same applies to the unexpected. A watchdog loop once found roughly six gigabytes of untracked working copies, ten repositories, all created the same afternoon by agents in the middle of an investigation. Nobody had asked it to look. It did not delete them and it did not stay quiet. It logged what it found, classified it correctly as active work, and flagged the disk use as a risk worth watching.
Silence is not a status
A coordinator once caught a worker that had been retrying the same rate-limited call for thirty minutes. The call was never going to succeed. The coordinator told it to mark the task blocked with a note and move to something that did not need a live server. Nobody was watching that terminal. The coordinator caught it because the worker’s state was visible in a shared store. A worker that goes quiet while technically still running is not making progress. A live process is not a status.
The same need for a checkable state is why every agent registers before it touches anything. At the start of a session it logs into the task system, takes an identity and announces itself. After that, the question of who is doing what right now has a real answer.
Standing duties work the same way. When an agent owns something ongoing, such as watching a subsystem and posting one digest, my follow-up is always the same: did you post it, and if so, what is the message ID. A claim is a self-report, the kind described in Agent self-reports are not evidence. A message ID pointing at a message in a store is evidence.
If it did not land in a store somebody else can query, it did not happen.
Why separate stores instead of one wiki?
Because a stray file is not a record. A file dropped in a home directory has no owner and no schema. Only someone who remembers its path can query it, a loop cannot check it, and nothing else in the fleet knows it exists. The stores have commands and an interface that other agents and tools can call.
They are plural on purpose. Tasks are not memories, memories are not conversations, and conversations are not knowledge. Each store answers a different question: what needs doing, what have we learned, what did we say to each other, what do we know. Collapse them into one wiki and you are back at stray files with a nicer folder name.
Memory gets structure too. Every session is distilled into a summary under three fixed headings: user preferences, reusable knowledge, and failures and how to do differently. The fixed headings are what make a hundred summaries searchable as one body of knowledge.
The record is held to its own standard
The database under our orchestration layer once began throwing lock errors under the load of its own fleet writing to it at the same time. The tool built to remember everything briefly could not keep up with the agents reporting to it. The fix was the same standard applied one layer down: durable storage that is safe under concurrent writes, as in Durable state for agents.
The clock is tested as well. A scheduler proves it is alive with a canary: a run that must reply with one exact string at one exact minute, after which the transcript is checked for that string. If the canary is late or missing, every timestamp downstream is suspect.
None of this bans thinking in prose. I dictate long, messy paragraphs of intent all the time, the way Voice-first specs describes. The rule is narrower: once a fact has to outlive the conversation that produced it, it moves into a store that is indexed, owned and queryable by name.